

Predictive models have always asked a lot of the people who use them. Before a marketer gets value from a prediction, they have to recognize that one is relevant, choose the right approach, configure it against their data, and judge whether the result is good enough for the campaign in front of them.
When we built Predictions into mParticle Agent, the conversational agent inside Rokt mParticle, the goal was to move more of that burden into the product. A marketer can start with “I want to reduce churn” instead of a model type, and the agent works out whether a prediction belongs in the answer at all.
Moving that expertise into the product created two design problems. Inside the system, we had to decide which part of the agent was allowed to make each decision. Between the system and the marketer, we had to decide how much judgment the product needed to supply now that the marketer no longer had to bring it. We started inside the system.
One prompt works until irrelevant instructions become a risk
mParticle Agent launched with one system prompt. It supported data exploration and audience creation, and all of its product judgment lived in one place. Splitting it earlier would have added routing, handoffs, and coordination without solving a real product problem, and it would have slowed down how quickly we could learn. If you’re starting to build an agentic system, start with one agent and make the system earn its complexity.
Predictions changed the equation. It brought a substantial set of new concepts, tools, states, prerequisites, and multi-step workflows, and we knew more capabilities would follow it.
Prompt length was a concern, but we hit a different limit first. A model working on one task increasingly had access to instructions written for several others. Those instructions weren’t wrong, but they were wrong for the decision in front of the model, and instructions carry authority. They tell the model what it may assume, which tools it may use, and what a good next action looks like. A workflow could understand the marketer’s language perfectly and still reach for the wrong product semantics or tool, because instructions from another capability were also present.
So we moved from one prompt to a routed system of shared and specialist behavioral components. Our test for splitting was whether the single prompt had started creating ambiguity about which judgment applied, and Predictions is where it did.
Coordination becomes part of the product
Narrower specialists reduced one kind of complexity and created another, because the system now has to decide who owns the next decision and how the customer’s larger goal survives the move.
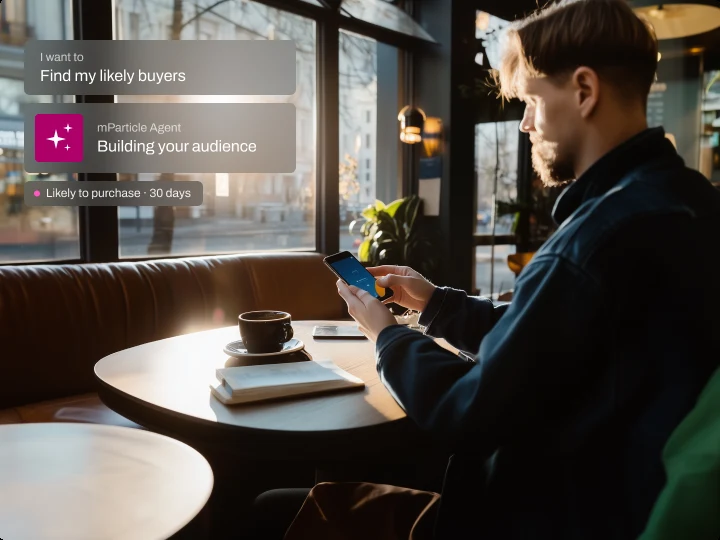
Take a marketer who asks for an audience of customers likely to purchase in the next 30 days. The output is an audience, but if no suitable predictive signal exists yet, the next decision belongs to Predictions. Routing on the word “audience” would send the request to a specialist that can’t responsibly act on it yet.
The routing question we settled on is which part of the system owns the first unresolved decision in the customer’s current goal, which also covers replies like “make it 60 days” that only make sense from the decision in progress.
Routing by decision also exposed a failure that first looked like a capability problem. Early on, a specialist would sometimes answer the half of a question it understood and explain that it couldn’t see the rest. The model understood the language, but it didn’t own the decision. The ability to answer isn’t the authority to answer.
Handoffs raised the same issue over time. A prediction takes time to become available, and when the marketer comes back, the agent needs to know why it was created and what’s still unfinished. We modeled context on how a good colleague remembers a project, keeping the goal, the decisions made, and what happens next rather than a transcript of every exchange. Once the prediction is ready, the agent returns to the audience the marketer asked for, because the prediction was a dependency and the audience was the goal.
None of this should be visible to the marketer. Internally, the agent is modular. Externally, the marketer works with one collaborator.
Self-service starts before anyone chooses Predictions
One collaborator also has to know what the marketer doesn’t, which is the second problem. The first place that shows up is before any model exists. A traditional predictive workflow starts after the customer has already decided a prediction is relevant, and that assumption breaks down when the goal is to make Predictions useful to marketers who wouldn’t have gone looking for them.
Take the marketer who wants to reduce churn. If they need customers who have already started cancelling, that’s a known-data question the CDP can answer directly. If they need customers likely to cancel next month, that’s an inference problem where a prediction can add value. And an existing prediction might already answer the question.
Because mParticle Agent works across customer data, audiences, and existing predictions, it can start with the business goal and check what the marketer already has before choosing a capability. The marketer doesn’t have to classify their own problem as a data, audience, or prediction question first.
Feature discovery used to mean helping customers find the right part of the product. With an agent, the product can find the right capability for the customer’s problem. That works in the other direction too. If known data answers the question, use it. If an existing prediction fits, reuse it. Inference belongs in the answer when it adds information the marketer doesn’t already have. The aim is to make Predictions easy to consider without making them the answer to every problem.
Better UX raises the product’s responsibility for judgment
The second place is after a prediction exists, when the marketer has to decide whether to use it. People who could configure a model on their own usually knew how to judge the result. They knew a model that calculated successfully wasn’t automatically right for every campaign, and they knew which metrics to check. Making configuration easy removes that accidental check, so a better experience can also make a bad decision more likely. The easier a powerful capability is to use, the more judgment the product has to supply.
Model quality shows why. It’s tempting to encode a simple rule where strong means proceed and moderate means stop. But model quality isn’t only a property of the model. It’s also a property of the decision the marketer intends to make with it. A prediction with moderate strength for an uncommon behavior might be worth testing in a low-cost exploratory campaign, and the same evidence might fall short for an expensive campaign where reaching the wrong customers carries a real cost. The metric stays the same while the decision changes.
So the question the agent has to answer is whether this prediction is good enough for what the marketer is trying to do. That means understanding the objective and bringing forward the evidence that matters for it, whether that’s strength, AUC, recall, or the available target range. If recall matters for the stated goal, the agent should raise it. The marketer shouldn’t need to know which technical question to ask.
Some complexity should disappear. Marketers shouldn’t need to know how each metric is calculated. Other complexity reflects real uncertainty, and hiding it would make the product less honest. A percentile isn’t an individual probability, predicted lift isn’t proof of causal impact, and a model that calculated successfully isn’t automatically right for the campaign. The agent keeps those distinctions visible and explains them in terms of the decision at hand.
The same principle applies to action, where mParticle Agent can recommend and prepare work, but consequential actions still need the marketer’s explicit confirmation.
Where judgment lives
Building Predictions into mParticle Agent started as a question about making a sophisticated capability easier to use. It became a question about where judgment should live.
Inside the system, we had to assign authority deliberately, so that shared behavior, specialist knowledge, routing, and context each had a clear owner. Between the system and the marketer, expertise moved the other way. The less a marketer needs to know to start, the more the product has to know on their behalf.
We expect the same two shifts to show up wherever an agent takes on work that used to require an expert. Moving complexity away from the customer only works if the judgment that complexity used to demand moves into the product with it.
The point of an agent isn’t to make expertise disappear. It’s to make expertise available without requiring the customer to bring it first.